Website crawl
Built, never run for a customerThe crawler works, is tested, can be started from the product, and stores what it finds. On 14 October 2026 the same code read every page of this site from the command line, while a crawl started from the product waits on the hosted worker being redeployed. No customer has ever run one.
What it will do
Before a page can be improved somebody has to read it. ShownTrue will take a domain, work out where its pages are, fetch them the way a search engine does, and keep a record of what each one said at the time.
Pages that only assemble themselves once JavaScript has run get a second pass through a real browser, and that decision is made per page rather than once for the whole site. Most pages never need it, and the ones that do are usually the ones that matter.
A crawl will be repeatable. Running it again next month and comparing the two is how a change to a site becomes visible without anyone having to remember what the page used to say.
The screen today
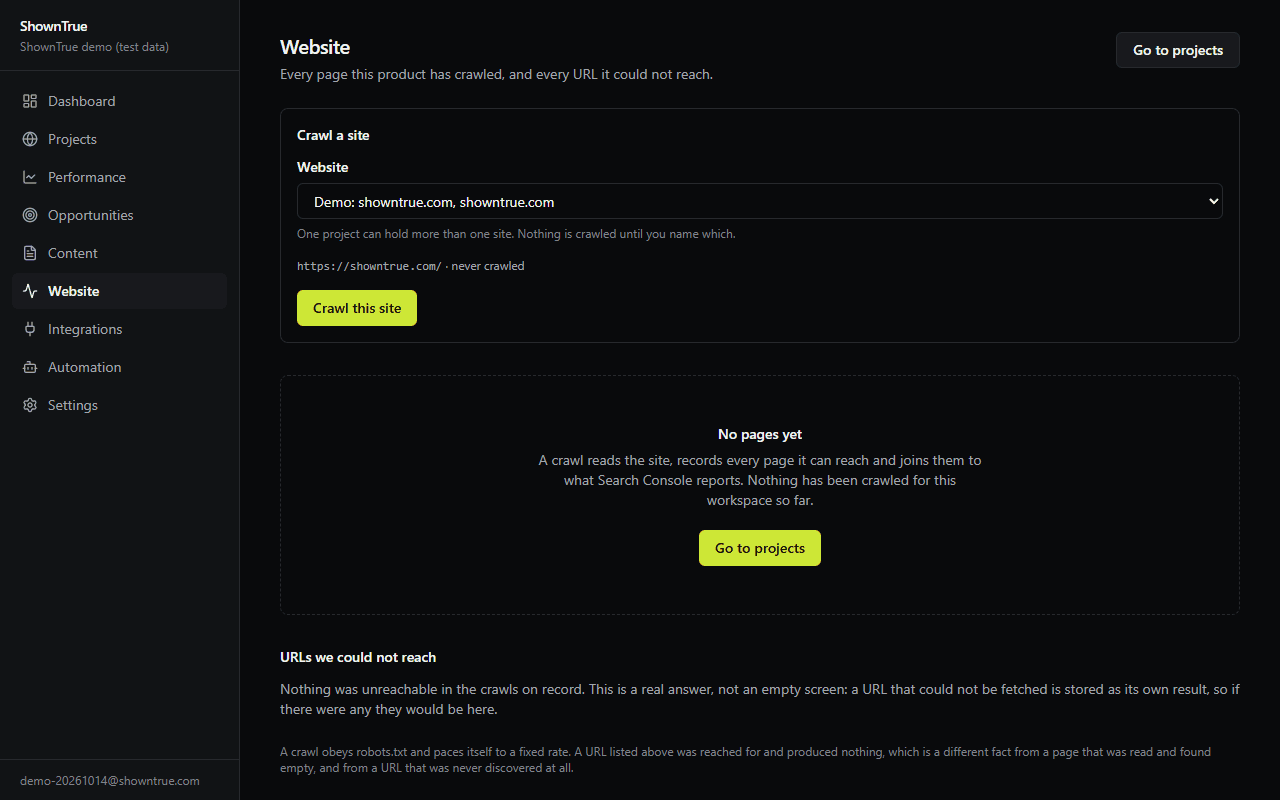
What exists today
- The crawler itself: fetching pages, finding them through the sitemap, obeying the rules a site publishes about what may be visited (the sitemap included), pulling out what each page says, deciding what to visit next, and a second pass through a real browser for pages that need JavaScript.
- A guard that refuses to fetch anything on a private or internal address, so pointing the crawler at your own network does not work. It is tested with the address cloud servers use to hand out their own credentials.
- The fetching code is tested against redirects into private addresses, sitemaps that loop or lie about their type, and the difference between a failure worth retrying and one that never will be. A whole crawl runs end to end against a test server we control.
- A screen that starts one, the action behind it, a background job, and storage: a run is written to the database as it goes rather than handed back and forgotten.
- Real crawls of this site over the internet. The first, on 9 September 2026, read ten pages with none failed. The latest, on 14 October 2026, read every page in the sitemap with none failed and recorded /sign-in, the one page it reached that asks not to be indexed; the home page shows its record.
What is missing
- Nothing recurs. A crawl happens when somebody presses the button. There is no schedule, so comparing this month against last month is a thing you have to remember to do.
- No customer has run one. Every crawl so far has been against this site, by us. What a real site with real problems does to it is unknown.
Measured against the code in this repository. When the code moves, this page moves with it, because both read the same list.